
By submitting, you consent to our use of your data. Privacy Policy.
Category
AI Agents
Share the article
If you build with Large Language Models, you already know the "LLM-as-a-Judge" playbook. As AI systems take on bigger tasks, you need a way to grade their outputs for accuracy, safety and relevance. The standard answer? Ask another LLM.
We hand a frontier model a prompt, an output and a rubric, and ask: "Is this answer accurate? Rate it from 1 to 5."
It works. But we are using a creative, generative text engine to do strict, analytical grading. Enter Jev, the "System One" decision model from TypeSafe AI. Jev cannot write a single word, and that is exactly what makes it a compelling new kind of evaluator: Jev-as-a-Judge.
The Problem with LLM-as-a-Judge
Using an LLM as an evaluator is like hiring a novelist as a building inspector. They can do the job, but they want to write a story about it.
That creates four friction points:
The parsing problem. To get a simple pass or fail, you write prompts like "Output ONLY valid JSON." Even then, the judge sometimes wraps its answer in chatter or breaks the format, and your pipeline breaks with it.
Confidence that is only words. Ask an LLM judge how sure it is and it writes a number. That number is text it chose to produce, not a measurement. In one test, an LLM judge used just six distinct confidence values across 88 cases, and was as certain about its mistakes as about its correct calls.
Latency. Generative models are bottlenecked by token generation. A judge that thinks out loud before writing
{"score": 4}adds seconds to every evaluation.Cost. Running a frontier model over every output, on every metric, in every CI run, adds up quickly.
Jev-as-a-Judge: A Judge That Only Gives Verdicts
Jev flips the paradigm. It does not predict the next word. It reads the context (the "state") and returns a typed decision with a probability attached to every possible answer.
To use Jev as a judge, you map each evaluation criterion to one of its three primitives:
Noul (yes/no): for pass/fail and safety checks. "Is this answer supported by the source document?" Jev returns a probability such as
0.02, not the word "No".Score: for graded rubrics. "Rate the relevance of this answer from 1 to 5." Jev returns a position on your scale plus the probability of each level.
Choice: for categories and comparisons. "Which answer is better, A or B?" or "Is the tone helpful, aggressive or neutral?"
Because the output is data, not language, it is exactly what an automated evaluator needs.

Both judges reject the wrong answer. The difference is what you can do with the result: Jev's 0.01 can be checked against labels and used as a threshold, while the LLM's "1" is simply what it chose to write.
The Advantages of Judging with Jev
OpenRouter put Jev head to head with an LLM judge (GPT-5.6 Luna) on 88 labelled faithfulness checks. Accuracy was a dead heat: 95.5% for Jev and 94.3% for the LLM. Everything else is where Jev pulls ahead.
1. Confidence you can actually trust
Jev's probabilities are calibrated. Its Brier score (lower is better) was 0.043 versus 0.054 for the LLM judge, and when Jev said above 0.8, the answer was acceptable 98% of the time. Genuinely ambiguous cases landed near 0.5, which is exactly where you want a human to look. It also held up better against padding: stuffing wrong answers with extra true sentences flipped three LLM-judge verdicts but just one of Jev's.
2. Zero parsing errors
Jev returns typed data, so there is no JSON to repair and no markdown fences to strip. It cannot break your format because it cannot write conversational text at all.
3. Fast enough to judge in real time
Generative latency grows with output length. Jev has no output tokens to generate. Its median response was 171 ms against 1,662 ms for the LLM judge, roughly 10× faster. That means Jev can run synchronously in the request path, grading a response before the user ever sees it.
4. A fraction of the cost
Jev costs $0.042 per million input tokens, and output is free. In the same test it cost $0.021 per 1,000 judgments versus $0.114 for the LLM judge, about 5× cheaper even against a budget model. Against premium frontier judges, the gap widens dramatically. Cheap enough that you can score every output instead of sampling.
Where the LLM Judge Still Wins
Jev is not a universal replacement. In the same study, when judges had to check whether a summary was consistent with a whole news article, the LLM judge tracked expert ratings far better (correlation 0.72 versus 0.47 for Jev). Claim-by-claim reasoning over long text is still a generative model's home turf.
Keep an LLM judge for open-ended rubrics you can't spell out, long documents, and any case where someone needs to read why an output failed. Jev gives you a verdict and a probability, never an explanation.
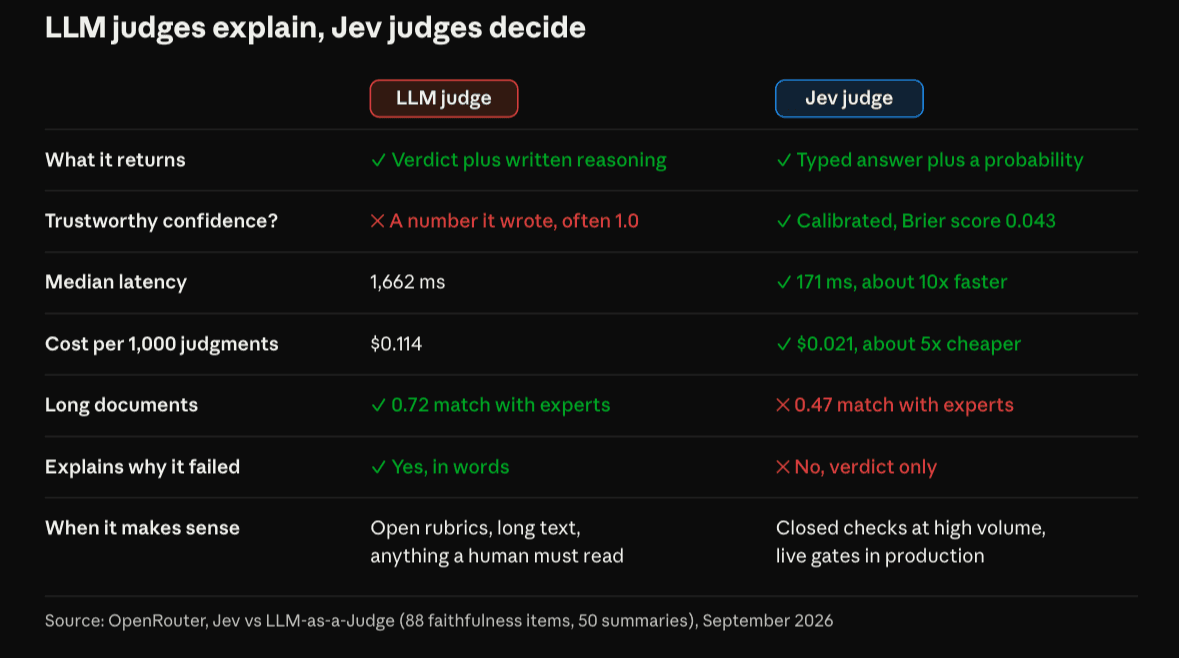
At a glance: Jev wins on trust, speed and cost for closed checks; the LLM judge wins on long documents and explanations.
The Verdict
LLM-as-a-Judge was a brilliant hack that let teams scale evaluation fast. But for the everyday checks that make up most of an eval suite, using a text generator as a strict grader is overkill.
The smartest setup is a judge cascade: Jev grades every output, confident verdicts are accepted, and only the uncertain middle is escalated to an LLM judge or a human reviewer. Research testing Jev against 13 LLM judges found it scored 99.8% on the items every LLM judge got right, with its errors concentrated exactly where its own confidence flagged them.
Getting started is easy, too. Jev already plugs into DeepEval, Langfuse, Arize and Promptfoo. Split compound rubrics into separate questions, label 50–100 of your own examples to set thresholds, and you are ready.
If you want to write a poem or draft an email, use an LLM. But if you need a fast, cheap judge that knows when it's unsure, it is time to put Jev on the bench.
Frequently Asked Questions
Can I just swap my LLM judge for Jev?
For many checks, yes. If the criterion is closed and the evidence is in the request, like "is this answer supported by the source?" or "does this reply follow our policy?", Jev is a drop-in fit. For open-ended quality judgments or long documents, keep your LLM judge.
Is Jev really as accurate as a GPT or Claude judge?
On closed checks, yes: OpenRouter measured 95.5% agreement for Jev against 94.3% for an LLM judge. Where Jev falls behind is long text that needs claim-by-claim reasoning, such as checking a summary against a full article.
How much will I actually save on evals?
It depends on the model you replace. Against a budget LLM judge, Jev came out about 5× cheaper ($0.021 vs $0.114 per 1,000 judgments). Against premium frontier judges the savings are much larger, since Jev charges only for input tokens.
What happens when Jev isn't sure?
That is where it shines. Jev's probabilities are calibrated, so unsure cases land near 0.5 instead of hiding behind a confident-sounding verdict. You can route just those cases to an LLM judge or a human, and auto-accept the rest.